OpenHarness | A Unified Framework for Evaluating LLM Agents
OpenHarness
Introduction
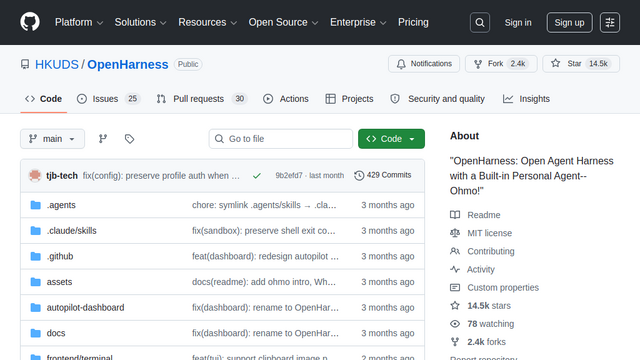
OpenHarness is a comprehensive, open-source framework designed to standardize and streamline the evaluation of Large Language Model (LLM) agents. It provides a unified interface and a suite of tools to measure the performance, reliability, and reasoning capabilities of AI agents across diverse tasks and environments.
Use Cases
Agent Benchmarking
Standardizing the performance testing of LLM agents against established datasets and custom scenarios.
Environment Integration
Connecting LLM agents to various external sandbox environments for real-world task execution.
Multi-Agent Evaluation
Assessing the collaborative performance and communication efficiency of multi-agent systems.
Workflow Debugging
Analyzing agent decision-making processes to identify bottlenecks or reasoning failures.
Research & Development
Providing a consistent framework for researchers to compare new agent architectures against baseline models.
Features & Benefits
Unified Interface
Offers a consistent API for interacting with different LLM agents and evaluation environments.
Extensible Framework
Allows users to easily plug in new benchmarks, environments, and agent models.
Comprehensive Metrics
Includes a library of metrics to evaluate task completion, efficiency, and safety.
Sandbox Support
Provides secure execution environments to test agent actions in isolated settings.
Open-Source Transparency
Fully accessible codebase allowing for deep customization and community-driven improvements.