PixelRAG | A Vision-Language RAG System for Multimodal Documents
PixelRAG
Introduction
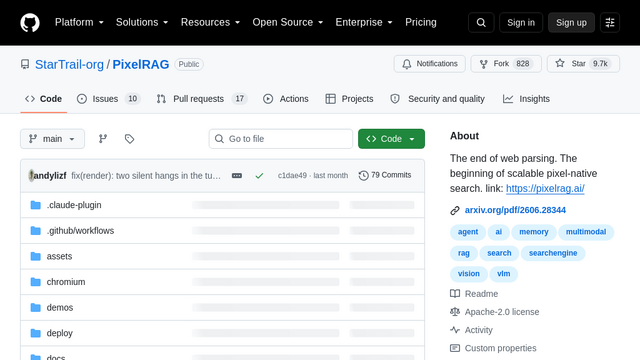
PixelRAG is an advanced open-source framework designed to bridge the gap between vision and language in Retrieval-Augmented Generation (RAG) systems. It specializes in processing complex, multimodal documents by leveraging vision-language models to extract and interpret visual information, ensuring high-fidelity retrieval and generation for documents containing charts, tables, and images.
Use Cases
Financial Report Analysis
Extracting and synthesizing data from complex financial tables and charts within annual reports.
Technical Documentation Retrieval
Retrieving specific diagrams or schematics from engineering manuals to answer technical queries.
Academic Research
Processing scientific papers that contain dense visual data and mathematical figures for literature reviews.
Legal Document Processing
Analyzing scanned legal contracts or documents that contain stamps, signatures, and handwritten annotations.
Multimodal Knowledge Base
Building a searchable knowledge base for organizations where information is heavily embedded in visual formats.
Features & Benefits
Vision-Language Integration
Utilizes state-of-the-art vision-language models to understand document layouts and visual content.
High-Fidelity Retrieval
Improves retrieval accuracy by considering both textual and visual context within a document.
Multimodal RAG Pipeline
Provides an end-to-end pipeline for indexing and querying documents that are not purely text-based.
Open-Source Flexibility
Allows developers to customize and integrate the framework into existing RAG architectures.
Layout Awareness
Maintains the structural integrity of documents, ensuring that visual elements are correctly associated with their surrounding text.